Integrating Predictive Models for Multi-Sport Accumulator Construction
Jordan Hansen · Oct 18, 2026
Integrating Predictive Models for Multi-Sport Accumulator Construction
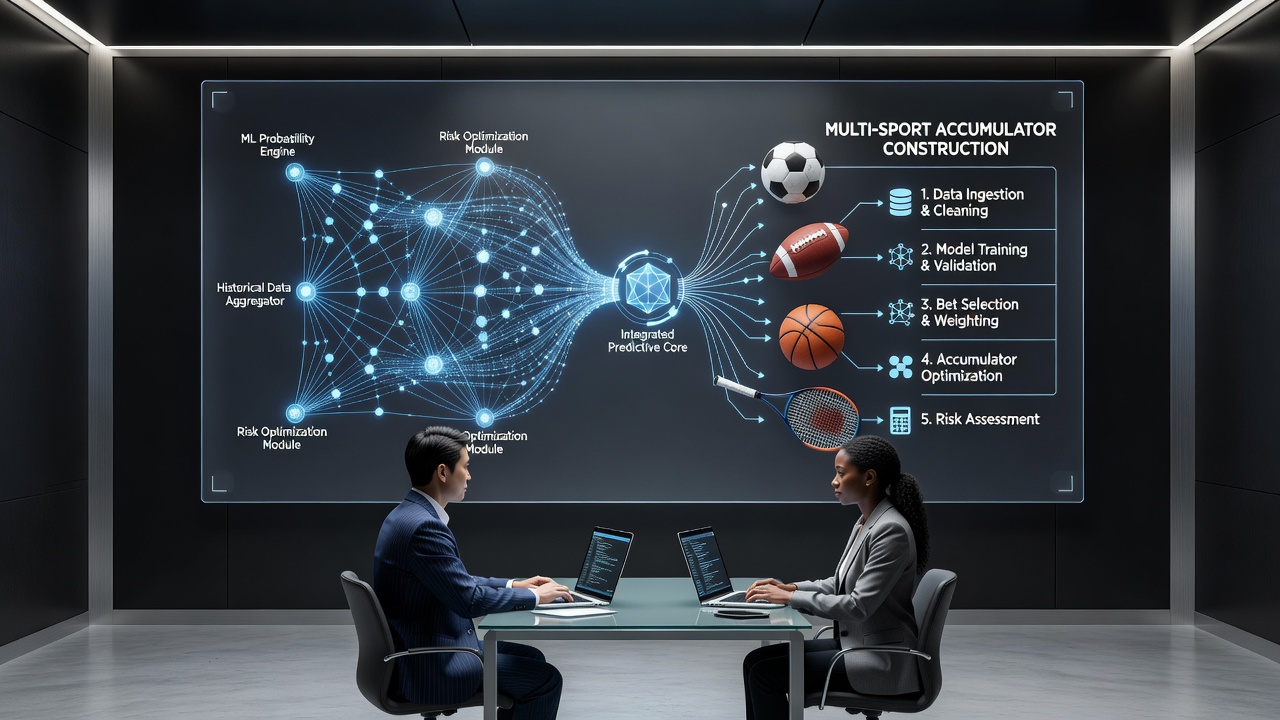
Experts in sports analytics have developed systems that combine machine learning algorithms with statistical frameworks to build accumulators spanning football, horse racing, basketball, and tennis; these approaches process historical performance data alongside real-time variables like weather conditions, player injuries, and track surfaces. Researchers at institutions such as the University of Nevada, Las Vegas have documented how ensemble methods merge outputs from separate sport-specific models into unified probability estimates, allowing bettors to chain selections across events that occur on the same day or over consecutive days.
Core Components of Predictive Integration
One model might evaluate football match outcomes using Poisson distributions for goal scoring while another applies logistic regression to horse racing place probabilities based on past form and jockey statistics; integration occurs through correlation matrices that adjust for shared factors like venue effects or market movements. Data shows these combined outputs reduce variance in accumulator odds when compared to standalone predictions, particularly when events involve different leagues or racing circuits. Observers note that feature engineering plays a central role, with variables such as expected goals in football aligned against speed ratings in racing through normalized scales.
Data Sources and Model Training
Training datasets often draw from public repositories maintained by sports governing bodies together with commercial tracking providers; academic papers from Canadian research groups highlight the value of incorporating macroeconomic indicators such as travel schedules or fixture congestion that influence multiple sports simultaneously. As of October 2026, several platforms have begun feeding live feeds from European and Australian competitions into cloud-based pipelines that retrain models weekly, and this practice supports more responsive accumulator construction when late team news emerges.
But here's the thing: correlation between sports remains modest in most cases, so weighting schemes become essential to prevent one high-confidence selection from dominating the overall probability calculation. Studies indicate that Bayesian updating techniques allow models to revise accumulator odds dynamically as new information arrives from earlier events in the chain.
Practical Construction Workflows
Analysts typically start by generating independent forecasts for each leg then apply copula functions to capture tail dependencies that standard multiplication overlooks; this step proves especially relevant when linking afternoon horse races with evening football fixtures across different time zones. Take one workflow where experts input form data into gradient boosting machines for racing and neural networks for team sports, after which a meta-learner synthesizes the results into a joint likelihood score. Figures from industry reports reveal that such layered architectures improve calibration on historical accumulator outcomes spanning 2018 through 2025.
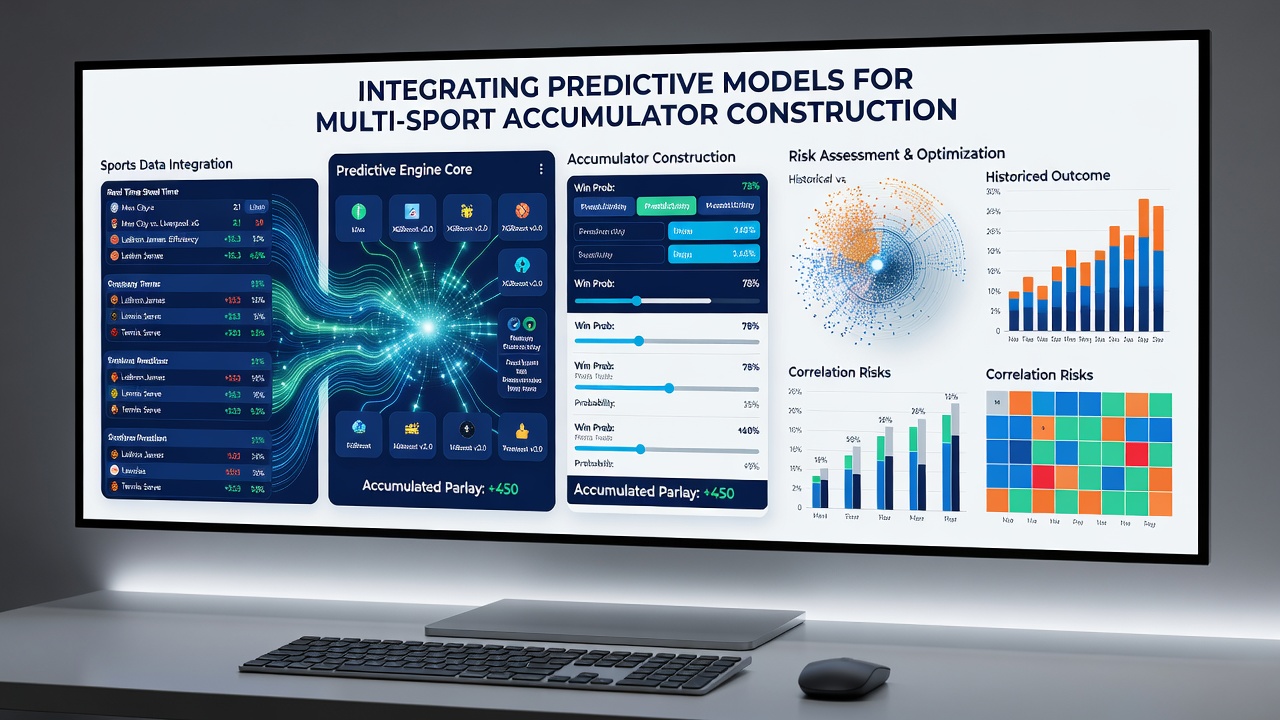
What's interesting is how practitioners handle edge cases such as simultaneous events where shared external shocks like major weather systems affect both racing fields and outdoor football pitches. Integration protocols often include scenario simulations that stress-test accumulators against correlated disruptions, and researchers have observed measurable gains in expected value when these simulations inform stake sizing decisions.
Challenges in Cross-Sport Model Fusion
Disparate data formats and update frequencies create friction during fusion, while regulatory differences across jurisdictions add another layer when models incorporate betting market odds as features. A report from the Australian Institute of Family Studies on gambling technologies notes that transparent model documentation helps operators meet emerging compliance standards in multiple regions. Those who manage large-scale systems emphasize the need for modular architectures that permit sport-specific retraining without disrupting the entire pipeline.
Yet integration also surfaces questions around computational cost, because running parallel simulations for dozens of potential accumulator combinations demands significant processing resources. Solutions involving cloud orchestration and selective sampling have gained traction, allowing teams to explore wider combination spaces while keeping latency manageable for users constructing bets in real time.
Future Directions and October 2026 Developments
By October 2026, several academic-industry partnerships had released open-source toolkits that standardize interfaces between football, racing, and basketball models, and early adopters report streamlined workflows for generating diversified accumulators. These toolkits incorporate reinforcement learning elements that optimize accumulator structures based on historical payout patterns across sports. Industry organizations such as the European Gaming and Betting Association have begun hosting workshops on ethical deployment of such systems, focusing on consumer protection features like automated risk disclosures.
Conclusion
Integration of predictive models for multi-sport accumulators continues to evolve through advances in statistical fusion and data infrastructure. Observers tracking developments across North America, Europe, and Australia note that success hinges on careful handling of inter-sport dependencies and ongoing validation against fresh outcomes. As datasets expand and computational methods improve, these approaches provide structured ways to assemble selections that draw from multiple athletic domains while maintaining statistical coherence.